OFFLINE CLASSROOM TRAINING IN PUNE • 7-MONTH DATA SCIENCE PROGRAM

From Raw Data to Production Machine Learning and GenAI.

Master practical statistical modeling, feature pipelines, modern algorithms (XGBoost, LightGBM), PyTorch neural networks, Generative AI (LLMs, RAG, Vector DBs), and MLOps deployment through hands-on labs, real messy datasets, and senior mentor code reviews.

7 Months / 28 Weeks
Pune Classroom Labs
Hindi + English Instruction
6 Production Capstones
Generative AI & RAG
Technical Interview Prep
Free 1-on-1 Profile Evaluation Inspect Real Student Portfolios No Obligation to Enroll
PUNE CAMPUS BATCH

Book a Free 1-on-1 Demo Session

Meet our lead Data Scientist in Pune. Experience our live coding approach and receive an honest career roadmap.

Please enter your full name.
We send demo batch confirmation & syllabus over WhatsApp.
Please enter a valid 10-digit Indian mobile number.

Your information is kept strictly confidential. No spam or aggressive calls.

Enterprise-Grade Methodology

Learn Data Science the Way Tech Companies Actually Build It.

Most courses teach toy datasets and isolated sklearn functions. At Two Dimension Institute, you learn end-to-end data science: from feature engineering on messy raw data to containerized Docker APIs and modern Generative AI knowledge systems.

Advanced Python & Data Ops

Master vectorized numerical computation with NumPy, memory-efficient Pandas pipelines, custom OOP classes, and automated data ingestion scripts built to process millions of rows cleanly.

NumPy Pandas OOP Python ETL Scripts

Applied Statistics & A/B Testing

Master the mathematical backbone of data science. Probability distributions, Central Limit Theorem, hypothesis testing (t-test, ANOVA, Chi-Square), p-values, and digital product A/B test analysis.

Hypothesis Testing A/B Testing Statsmodels Bayesian Math

Modern Supervised & Unsupervised ML

Derive and code mathematical models: Regularized Linear/Logistic Regression, Tree Ensembles (Random Forest, XGBoost, LightGBM, CatBoost), K-Means, DBSCAN, and PCA dimensionality reduction.

Scikit-Learn XGBoost CatBoost Optuna Tuning

PyTorch Deep Learning & Vision

Build multi-layer perceptrons from scratch, compute autograd gradients, train Convolutional Neural Networks (CNNs), utilize transfer learning with TorchVision, and evaluate classification metrics.

PyTorch CNNs Transfer Learning Autograd

Generative AI & Production RAG

Transformer architectures, tokenization, Hugging Face pipelines, vector embeddings, semantic vector search (ChromaDB, FAISS), and Retrieval-Augmented Generation (RAG) applications using LangChain.

Hugging Face LangChain ChromaDB RAG Pipelines

Production MLOps, FastAPI & Docker

Wrap trained ML and LLM models into low-latency REST APIs with FastAPI, validate requests with Pydantic, package into Docker containers, log runs in MLflow, and build Streamlit dashboards.

FastAPI Docker MLflow Model Monitoring
Clear Target Profiles

Is This Data Science Program Built for You?

Designed for ambitious learners who want practical, hands-on predictive engineering skills rather than surface-level theory. We meet you at your current level and build systematically.

College Students & Freshers

Graduates from B.E, B.Tech, BCA, MCA, or B.Sc (Math/Stats/CS) looking to bypass low-growth manual testing by mastering practical machine learning and generative AI engineering.

Launch career as Junior Data Scientist / ML Trainee

Data Analysts Upgrading to ML

Working with SQL, Power BI, or Excel and hit a salary ceiling? Advance into predictive modeling, algorithmic decision engines, and statistical machine learning.

Advance to Senior Data Scientist & ML Specialist

Software Developers & QA

Engineers with backend, web, or automation experience wanting to transition into high-growth applied AI engineering, LLM systems, and MLOps production pipelines.

Transition to Applied AI / MLOps Engineer

STEM & Career Switchers

Professionals from engineering, banking, finance, or operations with strong logical reasoning looking for a structured, mentor-led transition into data science.

Pivot into high-demand analytics & AI roles

Prior Background

No prior coding experience required. Module 1 starts from absolute zero Python syntax and algorithmic logic. Basic comfort with high-school math is all you need.

Hardware & Time Commitment

Any laptop with 8GB RAM (16GB recommended). We provide cloud environments for heavy training. Commitment of 8-10 hours/week for hands-on labs outside class.

Comprehensive Syllabus

28 Weeks of Systematic, Project-Led Data Science Curriculum

Every module is structured with mathematical intuition, live instructor coding, guided lab practice, independent assignments, and a concrete production deliverable.

Showing All 10 Comprehensive Career Modules (Beginner to Production MLOps)
01

Python for Data Science & Algorithmic Foundations

3 Weeks (40 Hours) Python 3.11+, OOP, Git Ingestion Engine

Transition from zero programming knowledge to writing clean, modular, object-oriented Python code capable of reading messy files, consuming web APIs, handling exceptions, and managing environments with Git and GitHub.

Core Topics & Practical Concepts

  • Python syntax, memory references, dynamic typing, primitive data types.
  • Collections: Lists, Tuples, Dictionaries, Sets and algorithmic time complexities.
  • Control flow: Conditional branching, while loops, for loops with enumerate/zip.
  • Functions: Parameters, *args, **kwargs, docstrings, scope (LEGB rule), pure functions.
  • Comprehensions: List, dict, and set comprehensions; lambda, map, filter.
  • Object-Oriented Programming (OOP): Classes, instances, inheritance, encapsulation.
  • Exception handling, custom error classes, logging best practices, file I/O (CSV, JSON, Parquet).
  • Virtual environments, pip package management, Git workflows, and GitHub repositories.
Practical Assignment
Build a modular, object-oriented Python library that reads incoming sales logs in CSV and JSON, performs automated schema validation, logs malformed records, and writes sanitized Parquet files.
Module Deliverable
Production Data Ingestion & Sanitization Utility published to a personal GitHub repo with automated unit tests.

Master the mathematical backbone of data science. Learn to validate business hypotheses with statistical significance, separate true signal from random noise, and design reliable digital product A/B tests.

Core Topics & Practical Concepts

  • Descriptive statistics: Central tendency (mean, median, mode) and dispersion (variance, std dev, IQR).
  • Probability: Independent vs conditional probability, Bayes' Theorem and posterior updating.
  • Distributions: Normal (Gaussian), Standard Normal (Z-score), Binomial, Poisson, Exponential.
  • The Central Limit Theorem (CLT) and inferential statistics foundations.
  • Confidence intervals, margin of error, standard error of the mean (SEM).
  • Hypothesis testing: Null (H0) vs Alternative (H1), Type I (alpha) and Type II (beta) errors.
  • Parametric tests: One-sample & two-sample t-tests, Paired t-tests, One-way ANOVA.
  • Non-parametric tests: Mann-Whitney U, Wilcoxon signed-rank, Chi-Square test of independence.
  • Product A/B testing: Statistical power, minimum detectable effect (MDE), sample sizing.
Practical Assignment
Analyze 85,000 user sessions comparing two checkout variations for an Indian retail platform. Compute statistical power, conduct two-proportion z-tests, and evaluate revenue per user with bootstrap sampling.
Module Deliverable
Executive A/B Test Decision Report with statistical confidence intervals and product rollout recommendations.

Extract, aggregate, and structure training features directly from relational databases using production-grade SQL queries, complex analytical window functions, and programmatic Python database connections.

Core Topics & Practical Concepts

  • Relational database architecture, ACID transactions, data normalization vs star schemas.
  • Complex multi-table joins: INNER, LEFT, RIGHT, FULL OUTER, and self-joins.
  • Subqueries (scalar, correlated) and modular Common Table Expressions (CTEs).
  • Window Functions: ROW_NUMBER(), RANK(), DENSE_RANK(), NTILE(), running totals.
  • Time-series lead/lag functions: Computing day-over-day growth and user session intervals.
  • Advanced aggregations: CASE WHEN, COALESCE, NULLIF, and date/timestamp manipulation.
  • Query optimization: Execution plan inspection (EXPLAIN ANALYZE) and B-tree indexes.
  • Connecting Python to PostgreSQL using SQLAlchemy for automated ML feature extraction.
Practical Assignment
Write a multi-stage SQL CTE pipeline on a 2.5M-row ride-sharing dataset in PostgreSQL to calculate monthly retention cohorts, repeat ride frequency, and rolling 90-day Customer Lifetime Value (LTV).
Module Deliverable
Automated SQL Feature Extraction Script integrated with Python for continuous model training.

Turn messy, incomplete real-world data into clean, robust features ready for machine learning algorithms. Master data storytelling through publication-quality visual diagnostics.

Core Topics & Practical Concepts

  • Pandas internals: DataFrames, Series, index alignment, vectorization vs slow loops.
  • Missing data strategies: MCAR, MAR, MNAR; mean/median, KNN, and iterative imputation.
  • Outlier management: Z-score thresholds, IQR fencing, winsorization, Isolation Forests.
  • Categorical encoding: One-Hot, Ordinal, Target Encoding, Weight of Evidence (WoE).
  • Feature scaling: Min-Max, Standard Z-scaling, Robust scaling, Log, Box-Cox transforms.
  • Domain features: Time deltas, cyclical encodings (sin/cos for hour/day/month), interaction ratios.
  • Multicollinearity diagnostics: Correlation matrices, Variance Inflation Factor (VIF).
  • Visual EDA with Seaborn & Plotly: Histograms, KDE, box/violin plots, pairplots.
Practical Assignment
Construct an enterprise-ready `ColumnTransformer` and `Pipeline` combining numerical imputers, robust scalers, target encoders, and custom transformers that completely prevents data leakage during cross-validation.
Module Deliverable
Reusable Scikit-Learn Data Preprocessing Pipeline Library with complete visual EDA audit notebook.

Build and rigorously validate core supervised machine learning models. Understand the mathematical trade-offs between bias and variance, and select optimal metrics for business problems.

Core Topics & Practical Concepts

  • Machine Learning formulation: Inputs (X), Targets (y), loss functions, empirical risk.
  • Linear Regression: Mathematical derivation of OLS, assumptions, residual diagnostics.
  • Regularization: Ridge (L2 penalty) for multicollinearity, Lasso (L1 penalty) for feature selection.
  • Gradient Descent: Batch, Stochastic (SGD), and Mini-batch optimization algorithms.
  • Logistic Regression: Sigmoid activation, log-odds, maximum likelihood, decision thresholds.
  • Instance-based: K-Nearest Neighbors (KNN), distance metrics, Naive Bayes classifiers.
  • Support Vector Machines (SVM): Maximum margin hyperplane, slack variables, kernel trick.
  • Regression metrics: MAE, MSE, RMSE, R-squared, Adjusted R-squared.
  • Classification metrics: Confusion Matrix, Precision, Recall, F1-Score, ROC-AUC, PR-AUC.
Practical Assignment
Build a regularized logistic regression and SVM model on 120,000 customer records. Analyze precision-recall curves to identify the decision threshold that maximizes retention profit while minimizing discount costs.
Module Deliverable
Calibrated Customer Churn Prediction Engine with full cost-utility threshold optimization matrix.

Discover hidden customer archetypes and anomalies in unlabelled datasets. Compress high-dimensional feature spaces while preserving maximum statistical variance.

Core Topics & Practical Concepts

  • Unsupervised learning paradigm: Finding structure without explicit target labels.
  • K-Means: Centroid updates, Voronoi cells, K-Means++ initialization, convergence.
  • Cluster validation: Within-cluster sum of squares (Elbow), Silhouette Score.
  • Hierarchical Clustering: Agglomerative vs Divisive, linkage criteria, Dendrograms.
  • DBSCAN: Core points, border points, noise handling, epsilon and min_samples tuning.
  • Curse of Dimensionality: Distance concentration in high-dimensional spaces.
  • Principal Component Analysis (PCA): Covariance matrix decomposition, eigenvalues/eigenvectors, scree plots.
  • Manifold learning: t-SNE and UMAP for non-linear dimensionality reduction.
Practical Assignment
Process behavioral RFM data for 250,000 retail app users. Apply PCA to reduce 45 features down to 5 orthogonal components, cluster users with DBSCAN, and label actionable persona profiles for CRM marketing.
Module Deliverable
Customer Persona Segmentation Engine with interactive PCA/UMAP visual cluster dashboard.

Master the algorithmic workhorses of enterprise tabular modeling. Train state-of-the-art boosted trees and explain their internal predictions using Game Theory (SHAP values).

Core Topics & Practical Concepts

  • Decision Trees: Recursive binary splitting, Gini Impurity, Entropy, pruning strategies.
  • Bagging Principles: Bootstrap aggregation, variance reduction, Out-Of-Bag (OOB) error.
  • Random Forests: Feature bagging, tree diversity, hyperparameter tuning.
  • Boosting Principles: Sequential residual learning, weak to strong learners, AdaBoost.
  • Gradient Boosting (GBM): Loss gradient descent in function space, learning rate.
  • XGBoost Architecture: Second-order Taylor loss expansion, tree regularization.
  • LightGBM & CatBoost: Histogram splitting, leaf-wise growth, native categorical handling.
  • Hyperparameter Optimization: Bayesian optimization with Optuna vs Grid Search.
  • Explainable AI: SHAP beeswarm and waterfall plots; LIME for regulatory audits.
Practical Assignment
Train an optimized LightGBM classifier on credit bureau applications. Run Bayesian tuning with Optuna, generate global feature importance, and output individual loan rejection SHAP waterfall explanation reports for RBI audit standards.
Module Deliverable
Explainable Credit Risk Scoring Engine compliant with financial transparency and regulatory standards.

Construct, train, and debug deep neural networks from first principles using PyTorch. Learn tensor operations, custom training loops, convolutional architectures, and transfer learning for computer vision tasks.

Core Topics & Practical Concepts

  • Perceptrons to Deep Networks: Hidden layers, universal approximation theorem.
  • Activation Functions: ReLU, LeakyReLU, GELU, Sigmoid, and vanishing gradients.
  • Backpropagation: Chain rule derivation, computational graphs, PyTorch autograd engine.
  • Optimizers: SGD with Momentum, RMSprop, Adam, AdamW, learning rate schedulers.
  • Regularization: Dropout, L2 weight decay, Batch Normalization, Early Stopping.
  • PyTorch Workflow: nn.Module, custom Dataset, DataLoader, writing modular training loops.
  • Convolutional Neural Networks (CNN): Kernels, stride, padding, feature maps, pooling.
  • Vision Architectures: ResNet residual skip connections, transfer learning in TorchVision.
Practical Assignment
Fine-tune a pretrained ResNet-50 network in PyTorch to classify pneumonia cases from a dataset of 5,800 medical X-ray scans. Implement data augmentations, class weighting for imbalance, and plot confusion matrices.
Module Deliverable
Medical Diagnostic Image Classifier with PyTorch model checkpoints and evaluation reports.

Master the GenAI stack modern enterprises demand. Learn how Transformer models work, run local open-source LLMs, generate vector embeddings, and construct end-to-end Retrieval-Augmented Generation (RAG) knowledge assistants.

Core Topics & Practical Concepts

  • Evolution of NLP: From Bag-of-Words and TF-IDF to modern Transformers.
  • Transformer Architecture: Self-attention, Q-K-V matrices, multi-head attention.
  • Hugging Face ecosystem: transformers library, tokenizers, running open-source models.
  • Prompt Engineering: Role assignment, few-shot prompting, chain-of-thought (CoT).
  • Vector Databases: Dense vector embeddings, cosine similarity, indexing with ChromaDB and FAISS.
  • Production RAG Architecture: Document chunking strategies, context injection, hallucination reduction.
  • LangChain & LlamaIndex: Building prompt chains, conversational retrieval agents, source attribution.
Practical Assignment
Build a complete RAG system that parses hundreds of internal enterprise policy PDFs, stores chunked embeddings inside ChromaDB, retrieves relevant passages, and prompts an LLM to generate precise answers with page citations.
Module Deliverable
Enterprise Document Q&A Assistant with RAG, vector search, and source-attributed responses.

Bridge the gap between Jupyter notebooks and enterprise software engineering. Package, deploy, monitor, and defend production-grade machine learning APIs and interactive dashboards before an industry panel.

Core Topics & Practical Concepts

  • MLOps Lifecycle: Data versioning, model reproducibility, and technical debt in ML.
  • Model Serialization: Saving and loading pipelines using joblib and ONNX safely.
  • REST APIs with FastAPI: Pydantic schema validation, async endpoints, Swagger docs.
  • Containerization with Docker: Dockerfiles, base images, port mapping, and container testing.
  • Experiment Tracking: Logging parameters, metrics, artifacts, and runs with MLflow.
  • Interactive Demos: Streamlit dashboard creation with live sliders and chart visualizers.
  • Model Monitoring: Detecting data drift, concept drift, and performance degradation.
  • Capstone Viva & Defense: Defending model choices, assumptions, trade-offs, and metrics.
Practical Assignment
Take a trained XGBoost fraud detection pipeline, wrap it in a high-speed FastAPI microservice, build a Docker container, write automated unit tests, and host an interactive Streamlit testing console for simulated payments.
Module Deliverable
Dockerized Fraud Detection Microservice with live Swagger docs and Streamlit testing console.
Tangible Experience

6 Substantial Industry Capstones You Will Build

No superficial tutorials or standard Titanic toys. Every capstone gives you realistic messy data, authentic business bottlenecks, and requires full-cycle analytical and predictive execution that recruiters can inspect.

FinTech & Telecom Project 01

Customer Churn Prediction & Retention Optimization

Analyze 150,000 subscriber usage and billing records to identify churn risk 30 days in advance. Perform cost-savings curve analysis to compute net customer retention ROI.

Stakeholder: VP of Retention & Customer Success
Tech Stack: Python, LightGBM, Scikit-Learn, SHAP, Streamlit
Key Challenge: Imbalanced classes and heavy categorical churn indicators
Key Deliverables
PR-AUC Optimization SHAP Waterfall Plots Streamlit Retention App
Banking & Credit Project 02

Credit Risk Scoring & Loan Default Probability Engine

Build an automated, mathematically defensible credit scoring engine on historical credit bureau applications with 120+ features, complying with regulatory transparency requirements.

Stakeholder: Chief Risk Officer (CRO)
Tech Stack: Python, PostgreSQL, XGBoost, Optuna, WoE/IV
Key Challenge: Regulatory compliance and explainability for rejected applicants
Key Deliverables
ROC-AUC (0.86+) Weight of Evidence Regulatory Audit Memos
E-Commerce & Retail Project 03

Dynamic Recommendation Engine (Collaborative Filtering)

Solve cold-start catalog bloat by combining Matrix Factorization (SVD) with content-based TF-IDF product similarity across 1.2M user rating interactions and product metadata.

Stakeholder: Head of Product Merchandising
Tech Stack: Python, Surprise, PyTorch, SciPy Sparse, Streamlit
Key Challenge: Extreme matrix sparsity and real-time inference latency
Key Deliverables
Precision@K Ranking Hybrid Filtering Interactive Catalog App
Healthcare & Vision Project 04

Medical Diagnostic Classifier with PyTorch

Fine-tune a ResNet deep neural network in PyTorch to classify pneumonia cases from 8,000 multi-class chest X-ray scans, with Grad-CAM heatmaps highlighting clinical regions.

Stakeholder: Clinical Radiology Team
Tech Stack: PyTorch, TorchVision, Albumentations, Grad-CAM, Docker
Key Challenge: Minimizing false negatives in critical diagnostic triage
Key Deliverables
High Sensitivity (Recall) Grad-CAM Heatmaps Containerized Model
Generative AI & LLMs Project 05

Enterprise Knowledge Q&A Assistant with Production RAG

Parse hundreds of internal compliance manuals and technical documentation. Embed text chunks into ChromaDB vector store and build conversational RAG retrieval with exact page citations.

Stakeholder: Legal & Compliance Operations
Tech Stack: LangChain, ChromaDB, OpenAI / Ollama Llama-3, Streamlit
Key Challenge: Preventing LLM hallucination on strict corporate policies
Key Deliverables
Dense Vector Search Page Citations Conversational RAG UI
MLOps & Serving Project 06

Real-Time Fraud Detection Microservice with Docker & FastAPI

Wrap a trained XGBoost fraud detection pipeline into a high-speed REST API microservice with Pydantic schema validation, sub-35ms response latency, and Docker packaging.

Stakeholder: Payment Gateway Engineering
Tech Stack: FastAPI, Docker, MLflow, Scikit-Learn, Pydantic
Key Challenge: Ultra-low latency serving on imbalanced streaming data
Key Deliverables
P99 Latency <35ms Docker Container MLflow Logging
Proven Pedagogical Model

The 6-Phase Practitioner Learning Workflow

Mastering machine learning requires active coding, mathematical intuition, and software engineering discipline. Our offline classroom loop ensures every concept is tested and verified.

1

Mathematical Intuition

Visual, geometric walkthrough of loss functions, gradients, probability, and matrix algebra in Hindi/English.

2

Live Classroom Code-Along

Instructor live coding on projector displays. Experience real debugging, package conflicts, and logic refactoring.

3

Daily Lab Challenges

Immediately apply the lesson on curated dirty datasets. Timed coding exercises simulating interview screenings.

4

1:1 GitHub Code Reviews

Senior mentors review your GitHub pull requests. Receive line-by-line feedback on modularity, vectorization, and tests.

5

Capstone Project Defense

Defend model trade-offs, metrics, and deployment architecture in classroom viva sessions before industry practitioners.

6

Technical Interview Readiness

Algorithmic Python coding tests, ML system design whiteboarding, and realistic panel mock interviews.

Transparent Evaluation & Certification Framework

Certificates are awarded based on verified demonstration of skills, not mere attendance.

25%
Lab Assignments
35%
Capstone Projects
20%
Mid-Term Assessments
20%
Capstone Viva Defense
Structured Career Preparation

Bridging the Gap from Learning to Hired.

Getting hired as a Data Scientist in today's competitive market requires more than just knowing syntax. We prepare you across every stage of the technical screening pipeline.

ATS-Optimized Technical Resume

Engineered with quantifiable project metrics: dataset volumes, cross-validation scores, and business outcomes that pass ATS filters.

Production GitHub Portfolio

Publish clean repositories complete with architecture diagrams, requirements.txt, Dockerfiles, and usage examples that recruiters love.

3-Tier Technical Mock Interviews

Simulated technical rounds: (1) Live Python & SQL coding, (2) ML algorithm intuition & math viva, and (3) System design & capstone defense.

Direct Hiring Pipeline

Direct connection to our network of hiring partners, analytics consulting boutiques, Pune/Bengaluru startups, and alumni referrals.

Transparent Institute Policy

Our Anti-Gimmick Placement Policy & Code of Ethics

In the Indian training landscape, institutes often use deceptive "100% Job Guarantee" slogans with hidden asterisks, or bundle non-technical telecalling jobs to claim high placement rates. We strictly reject these practices.

What we guarantee is uncompromising educational depth: an industry-grade curriculum, 350+ hours of rigorous classroom instruction, 6 production capstones, personalized 1:1 code reviews, and comprehensive interview preparation until you are placed. Your job offer is earned through your genuine skill, portfolio strength, and technical competence.

Authorized Two Dimension Institute Certification awarded upon Capstone Defense.
View Real Placed Alumni Stories
Expert Guidance

Learn from Active Data Science Practitioners

Our mentors are working data specialists who bring actual enterprise architectures, production pitfalls, and real hiring standards into the classroom every day.

Principal Data Scientist

Lead Program Architect • 11+ Years Experience

Former analytics lead at Tier-1 MNCs. Architected fraud detection engines, customer lifetime value models, and real-time recommendation platforms processing 10M+ daily events.

Statistical Modeling XGBoost & LightGBM A/B Testing System Design

Staff AI & MLOps Engineer

Deep Learning & GenAI Lead • 8+ Years Experience

Specializes in PyTorch neural architectures, Large Language Model RAG pipelines, and deploying low-latency model inference microservices with FastAPI and Docker.

PyTorch LangChain & RAG FastAPI Docker & MLOps

Placement & Technical Coach

Mock Interviews & Portfolio Reviews

Conducts weekly technical mock interviews, reviews ATS resume drafts, evaluates GitHub code repositories, and tracks each student's career transition roadmap.

ATS Resumes Technical Mocks GitHub Audits Career Strategy
Tangible Output

The Standard of Work You Will Produce

Here is an illustrative preview of the actual enterprise ML dashboard complexity, data pipeline depth, and mathematical rigor built during the 7-month program.
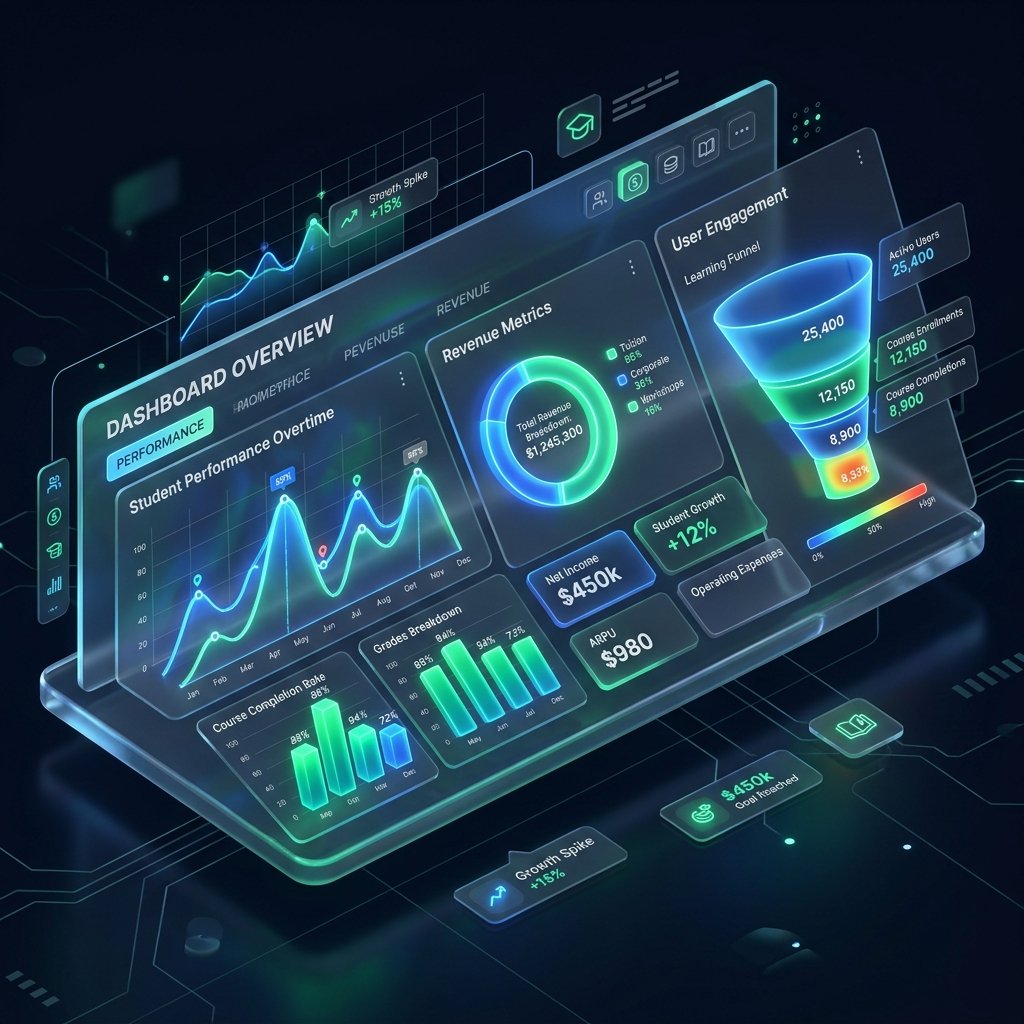
Illustrative Enterprise Machine Learning Dashboard and Model Diagnostics built by Two Dimension students

Real-Time Machine Learning Diagnostic & SHAP Console

Fully interactive Streamlit dashboard tracking live predictions, confusion matrices, ROC-AUC curves, and individual feature SHAP waterfall contributions.

Production Deliverables

What Goes on Your Candidate Portfolio

When recruiters review your application, they won't just see a resume with tool names. They will inspect public, working evidence of your data science problem solving:

  • Curated GitHub Repositories: Modular Python files, documented .sql scripts, and reproducible Jupyter notebooks.
  • Live Streamlit & FastAPI Apps: Cloud-deployed interactive demos allowing recruiters to run live model inferences.
  • Executive Architecture Docs: Clean READMEs with Mermaid diagrams explaining end-to-end data pipelines.
  • Regulatory Explainability Reports: SHAP and LIME waterfall plots justifying model decisions for non-technical stakeholders.
Explore Alumni Placement Stories
Clear Answers

Frequently Asked Questions

Everything you need to know about the curriculum, classroom environment, mathematics prerequisites, and institute policies.

1. I have no prior programming background. Can I succeed in this Data Science program?
Yes, absolutely. Module 1 starts from ground zero: variables, collections, loops, and modular functions. We do not assume you have written code previously. We have successfully trained graduates from non-IT backgrounds (B.Sc, B.Com, mechanical engineering, sales) who transitioned into data roles through structured lab practice.
Online courses have less than a 7% completion rate because they lack accountability and real code reviews. At Two Dimension Institute: you learn in an offline classroom in Pune with peers; you write code live alongside senior data scientists who review your GitHub pull requests; you work on messy, uncleaned datasets; and you face simulated technical mock interviews before an expert panel.
A Data Analyst focuses on descriptive and diagnostic analytics: querying databases with SQL, building Excel/Power BI dashboards to answer "What happened and why?" A Data Scientist focuses on predictive and prescriptive modeling: applying statistical mathematics, training machine learning algorithms (XGBoost, PyTorch), deploying APIs, and using Generative AI to answer "What will happen next and how should the system automate decisions?"
The industry demand for Data Scientists has fundamentally evolved. Companies no longer hire professionals who only know classical regression and decision trees. Organizations expect modern data scientists to understand Transformer architectures, generate vector embeddings, connect vector databases (ChromaDB/FAISS), and build Retrieval-Augmented Generation (RAG) applications that unlock value from unstructured enterprise documents.
You need comfort with high-school mathematics: basic algebra and percentages. We teach the required college-level mathematics—linear algebra (vectors/matrices), calculus (gradients/derivatives), and probability distributions—intuitively from first principles with visual geometric aids, showing exactly how each equation translates into working Python code.
Any standard modern laptop with at least 8GB of RAM (16GB recommended) and an Intel Core i5 or AMD Ryzen 5 processor is sufficient. You do not need to buy an expensive gaming laptop with an NVIDIA GPU. For heavy deep learning and transformer fine-tuning labs, we guide students through free and structured cloud GPU environments like Google Colab, Kaggle, and cloud instances.
We do not make false 100% job guarantee claims, as no legitimate educational institute can ethically promise an offer letter on behalf of an independent hiring employer. Instead, we provide 100% placement support: ATS-optimized resume engineering, technical mock interview clinics, portfolio defense sessions, direct referrals to hiring partners, and scheduled recruitment drives in Pune and Bengaluru.
Our flagship program is conducted in-person at our modern Pune campus (Shivajinagar). In-person learning fosters peer collaboration, uninterrupted lab focus, and immediate instructor debugging. For working professionals who cannot commute on weekdays, we offer specialized hybrid weekend batches with live interactive sessions and weekday lab mentoring.
All classroom lectures, code repositories, and lab walk-throughs are documented and recorded. If you miss a class, you can watch the recording, review the lesson code notebook, and book a 1:1 catch-up session during our weekly mentor doubt clinic to ensure you never fall behind.
Capstones are evaluated on four key pillars: (1) Problem Formulation & Exploratory Rigor, (2) Algorithm Selection & Cross-Validation Hygiene (checking for data leakage), (3) Production Engineering Standards (FastAPI serving, Docker packaging, clean Git history), and (4) Oral Defense during mock viva interviews where you explain your decisions to an industry mentor.
Yes. You can opt for our flexible 3-stage milestone installment plan: Stage 1 (₹15,000 at admission), Stage 2 (₹18,000 at end of Month 2), and Stage 3 (₹16,999 at end of Month 4). Additionally, zero-interest No-Cost EMI options are available across 6, 9, or 12 months with approved banking partners starting at ₹4,166/month.
Yes. Upon passing all module lab assessments, submitting 6 verified capstone repositories, and clearing the final project viva, you are awarded the Two Dimension Certificate of Completion in Data Science, Machine Learning & Generative AI with a unique verification URL and credential ID shareable on LinkedIn.
While R remains popular in academic biostatistics, Python is the undisputed global industry standard for production data science, machine learning, and AI engineering. Python seamlessly connects data wrangling (Pandas), classical ML (Scikit-Learn), deep learning (PyTorch), generative AI (Hugging Face / LangChain), and production deployment (FastAPI / Docker), making it the language 95%+ of companies hire for.
Simply fill out the quick lead form at the top of this page or click the "Book a Demo" button. Our academic counseling team will contact you via WhatsApp/call to understand your background, confirm your preferred time slot, and reserve your complimentary 1-on-1 demo seat at our Pune campus.
NEXT PUNE CLASSROOM COHORT STARTING SOON

Transform Your Career with Production Data Science & GenAI Skills.

Reserve your seat for an upcoming in-person demo session in Pune. Experience our live coding approach, inspect student capstone repositories, and receive a personalized learning roadmap.
100% Free 30-Min Counseling No Upfront Financial Commitments Direct Instructor Interaction